ETL
Extract
Transform
Load process
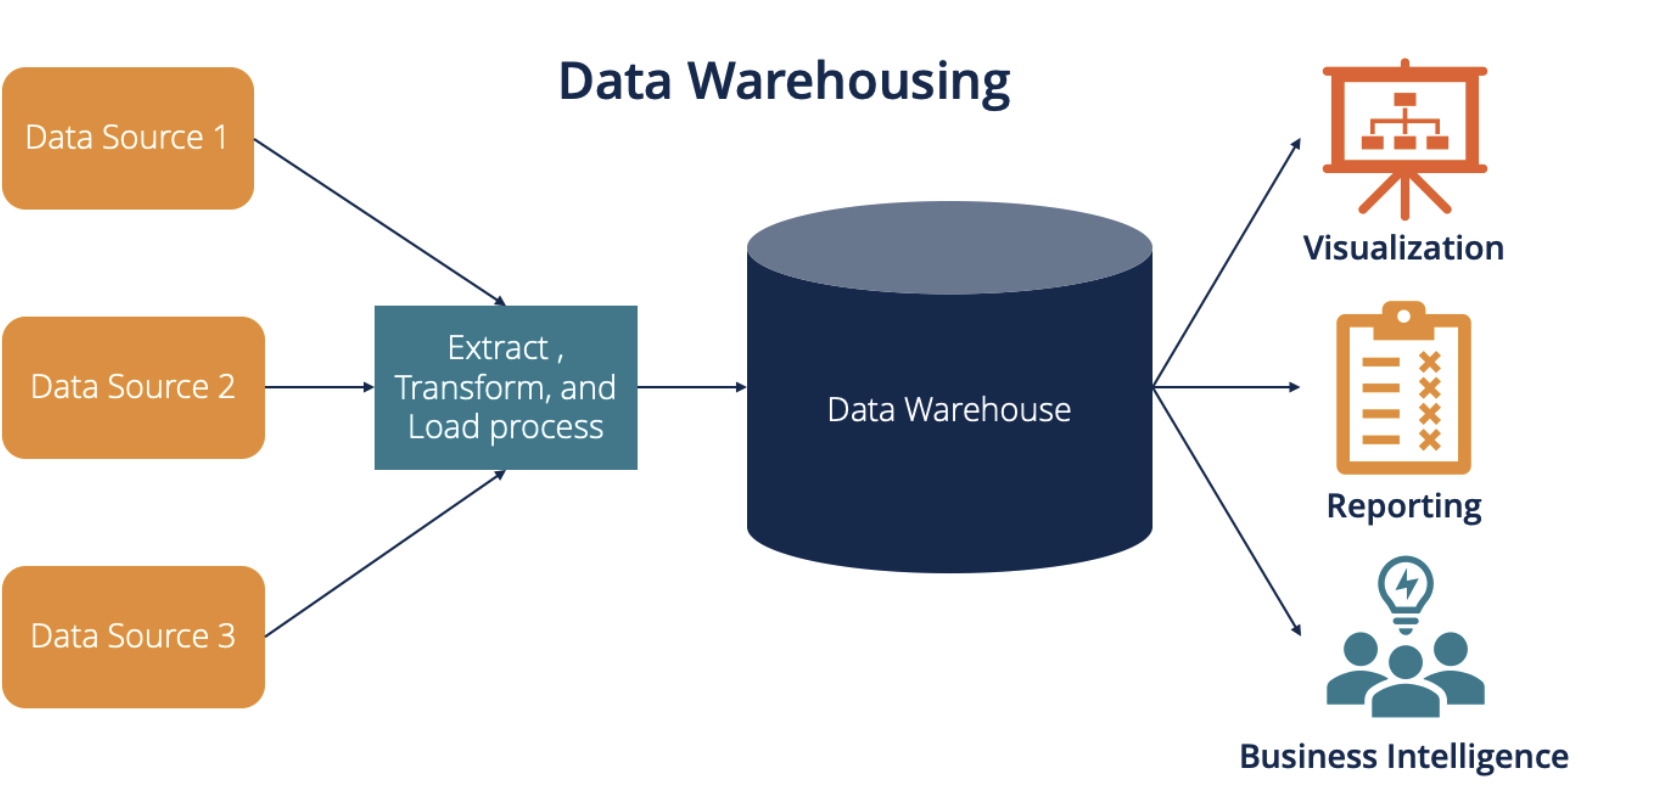
Design Data Warehouse
- requirement: business objectives, KPI and data sources
- schema design
- choose platform: snowflake, Redshift, bigquery
- ETL/ELT processes: Designing pipelines to handle high volumes of data while ensuring data quality.
- Performance optimization: Implementing indexing, partitioning, and caching strategies for fast query execution.
Maintain Data Quality
- understand data pattern/type from each data sources,
- validate data during ETL process to check for errors, when new data comes in
Optimize Query Performance
- indexing: create indexes for quickly look up
- partitioning: partition large data into small data
- materialized view: pre-compute and store results for repetitive queries
- Denormalization: reduce joins by consolidating data
Materialized View
pre-compute query results for future use
- less computational cost, no need to recompute each time
- can be refreshed incrementally to maintain up-to-date data
e.g pre-aggregate daily sales data in a sales reporting system, allowing faster and real-time analysis and visualization during peak hours
Incremental Loading
a technique that to update only new data or changed data
- timestamp: add last modified to identify if data is changed or new imported
- change data capture: detect and extract directly from data source via database logs or a triggers
- Compare current data with previously loaded data to identify changes.